-
Type:
Task
-
Resolution: Fixed
-
Priority:
 Major
-
None
-
Affects Version/s: None
-
Component/s: webdav
-
Security Level: Public (Visbile by non-authn users.)
-
None
On April 30th, ATLAS opened a GGUS ticket to INFN Tier1 reporting problems when contacting StorRM WebDAV after 8pm: "The requested service is not available at the moment. Details: An unknown exception occurred. Details: DavPosix::unlink Result (Neon): SSL handshake failed: Connection timed out during SSL handshake after 1 attempts".
ATLAS has two dedicated StoRM WebDAV endpoints (xfer-1 and xfer-2), where no other service is running. Both endpoints have been upgraded to CentOS7 a month ago (storm-webdav-1.2.1-1.el7.noarch).
At the time when the ticket was opened, I checked the status of the service on both endpoints, and found many "java.io.IOException: Too many open files" in /var/log/storm/webdav/storm-webdav-server.log on xfer-1 (and not on xfer-2).
Not only in the log files, but also when asking for the status of the service I could see "Too many open files" (on xfer-1, not xfer-2).
These are the limits of the process:
[root@ds-816 ~]# cat /proc/14823/limits
Limit Soft Limit Hard Limit Units
Max cpu time unlimited unlimited seconds
Max file size unlimited unlimited bytes
Max data size unlimited unlimited bytes
Max stack size 8388608 unlimited bytes
Max core file size 0 unlimited bytes
Max resident set unlimited unlimited bytes
Max processes 513412 513412 processes
Max open files 65535 65535 files
being them derived from the file (as discovered a month ago for CentOS7, you sure remember) /etc/systemd/system/storm-webdav.service.d/filelimit.conf:
[Service]
LimitNOFILE=65535
The file is the same in both xfer-1 and xfer-2; the limits of the process are also the same.
A restart of the service (in xfer-1) seems to have solved the issue.
But hopefully you can help us to understand why only one server started logging "Too many open files" and became unreachable.
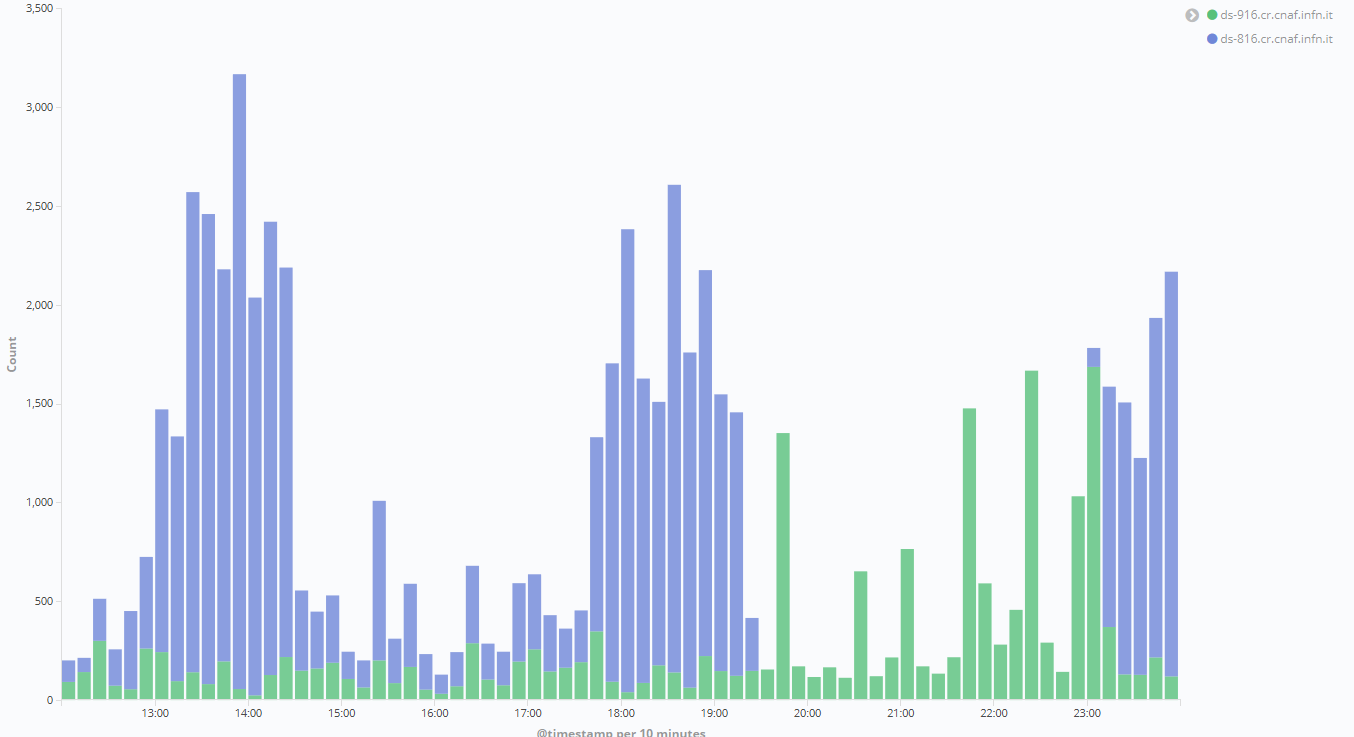
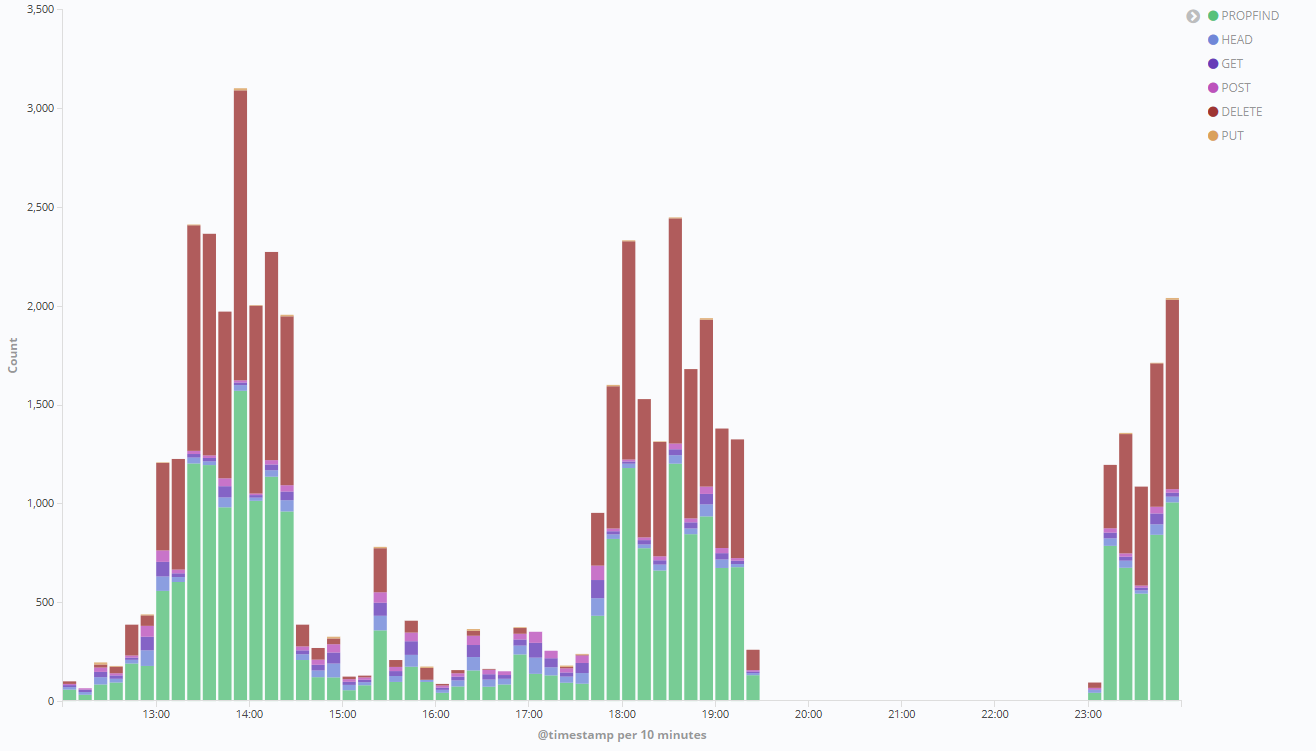
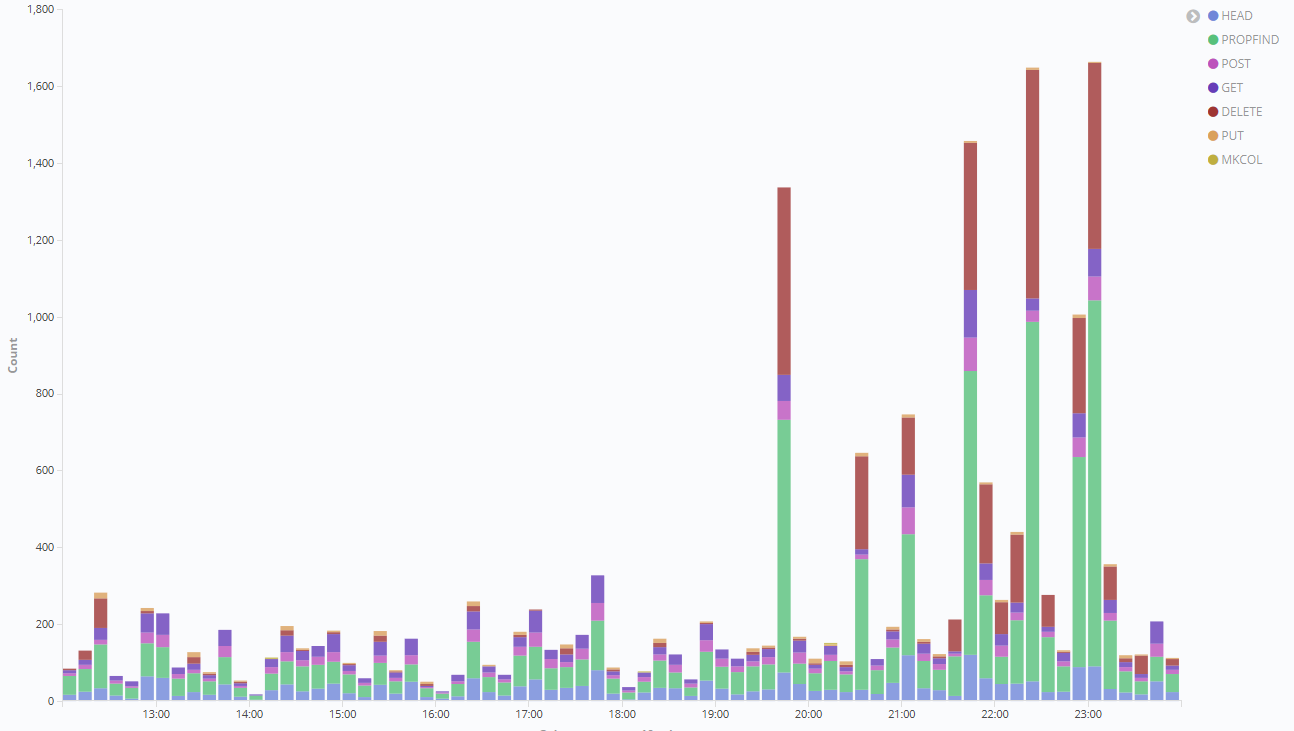
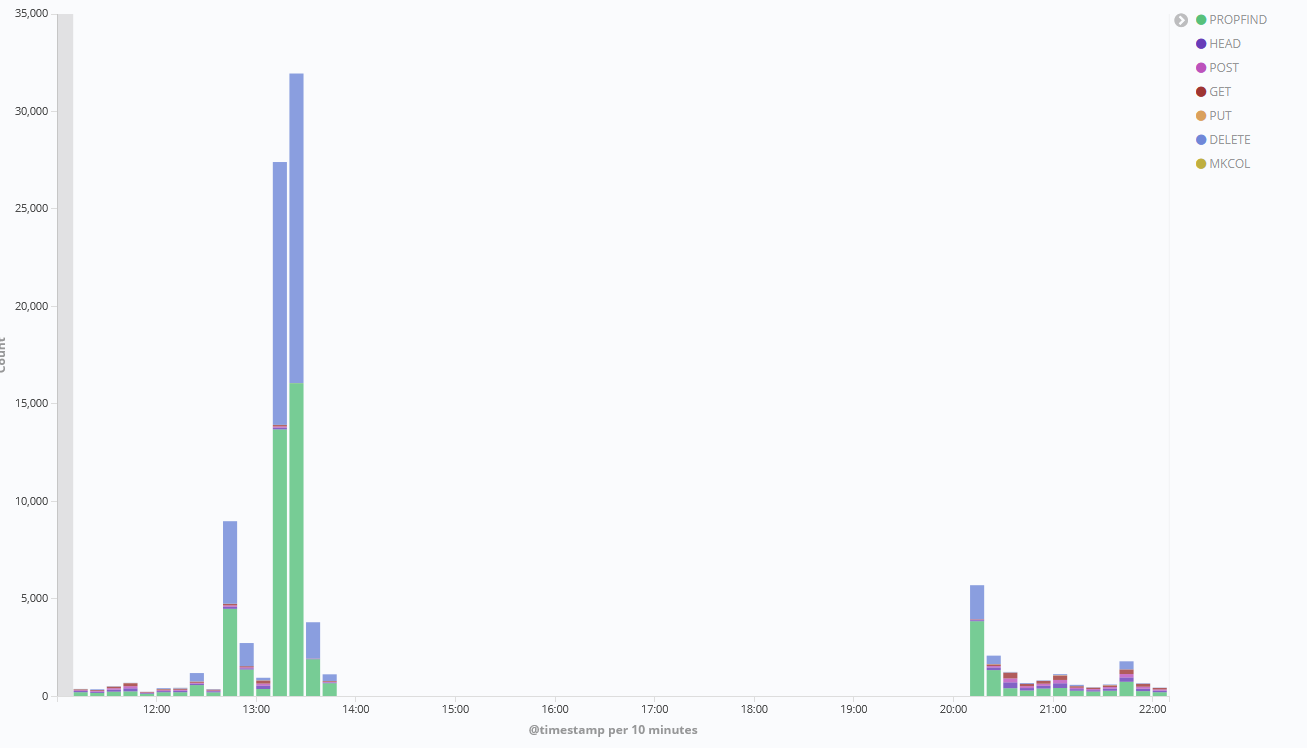
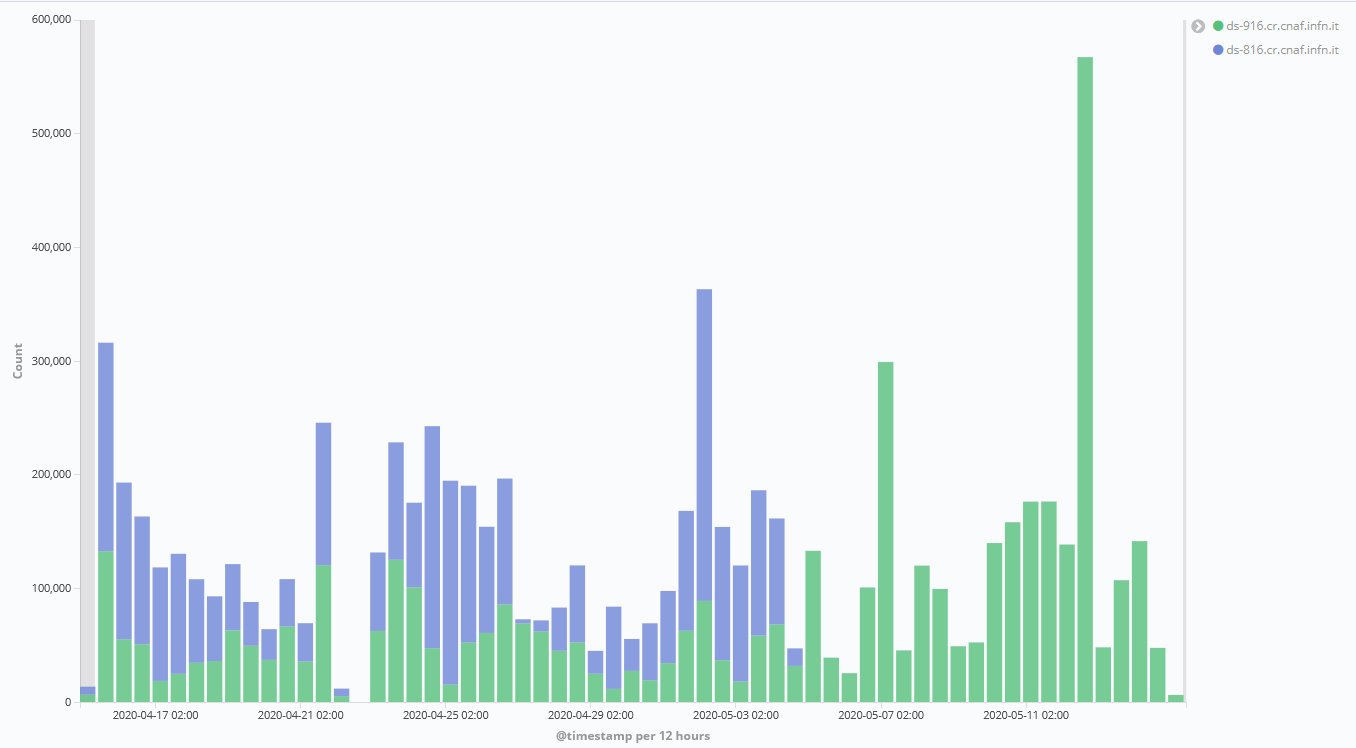
I attach the number of requests managed by both endpoints on that day, which were not too many I think. [The plot also shows how unequally the requests are shared between the two endpoints - this in unfortunately true at any time, and I believe it is a consequence of load balancing with DNS (any suggestion?).]. I also attach the methods requested to both endpoints on that day.
As usual, thank you very much for helping us,
lucia
- relates to
-
-
- Closed
-